Compiled by Nadia Yun. Published November 20, 2026 · Last updated November 20, 2026 · Pricing checked 20 Nov 2026.
The best LLM evaluation tools in 2026 share the same core features. What separates them is the bill: five vendors, five billing units.
TL;DR: All five have a free tier, so choose on billing unit and hosting: seats (LangSmith), units (Langfuse), spans (Arize), GB plus scores (Braintrust) or GB-months (Confident AI).
- LangSmith — best for LangChain and LangGraph teams
- Langfuse — best for free, open-source self-hosting
- Arize — best for OpenTelemetry-native production monitoring
- Braintrust — best for eval-gated prompt releases
- Confident AI — best for pytest-style test suites
Evaluation vs observability: evaluation scores model outputs against a standard before and after release; observability records what the model actually did in production, call by call.
Methodology & sources
- Prices, licences and features read from each vendor's pricing page, docs and GitHub on 20 Nov 2026; no benchmarks run.
- Criteria: eval depth, tracing, prompt management, cost tracking, self-hosting, published overage.
- Disclosure: this is Aissist's blog; Aissist sells customer-service AI agents and competes with none of these vendors.
How do the best LLM evaluation tools compare?
All five cover tracing, prompt management and cost tracking; they differ on licence, self-hosting and price. Only Langfuse's full platform is free to self-host under MIT; Arize's Phoenix uses the source-available Elastic License 2.0.
| Tool | Eval or observability | Open source | Self-host | From (paid) | Tracing | Prompt mgmt | Cost tracking | Checked |
|---|---|---|---|---|---|---|---|---|
| LangSmith | Both | No | Enterprise only | $39/seat/mo | Yes | Yes | Yes | 20 Nov |
| Langfuse | Both, observability-first | Yes, MIT | Free | $29/mo | Yes | Yes | Yes | 20 Nov |
| Arize | Both, observability-first | Phoenix, ELv2 | Phoenix free; AX Enterprise | $50/mo | Yes | Yes | Yes | 20 Nov |
| Braintrust | Both, eval-first | No | Enterprise only | $249/mo | Yes | Yes | Yes | 20 Nov |
| Confident AI | Eval-first | DeepEval, Apache 2.0 | Enterprise on-prem | $200/mo | Yes | Yes | Yes | 20 Nov |
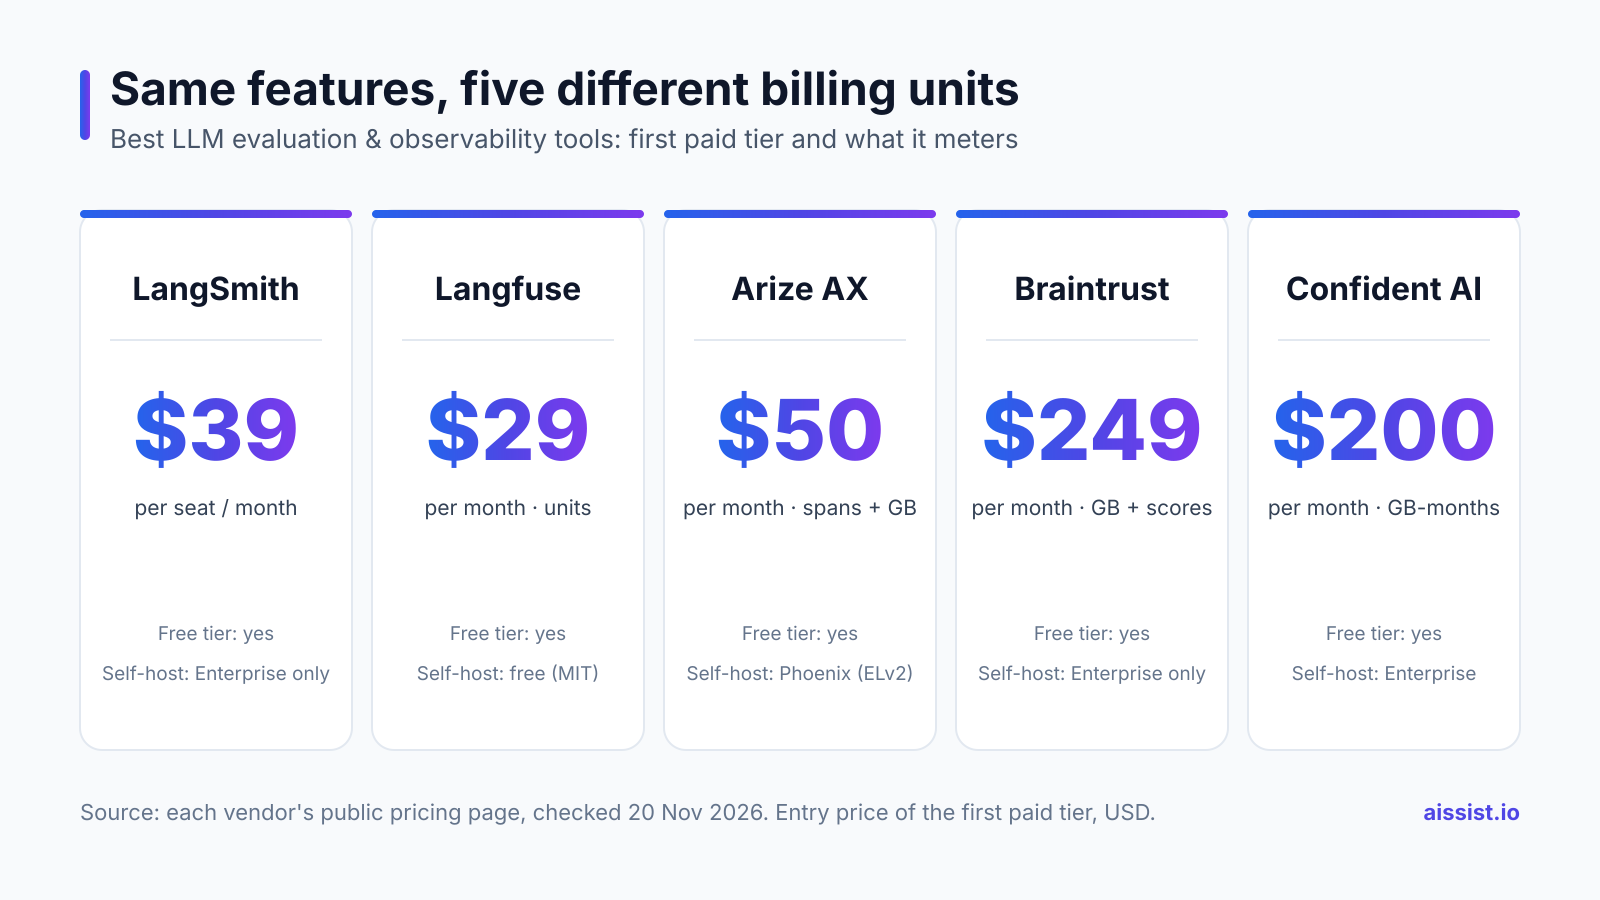
What does each LLM eval platform actually cost?
Entry prices run from $29 to $249 a month, but the billing unit decides what you pay at scale. Seat pricing grows with your team; data pricing grows with your traffic.
| Tool | Free tier | First paid tier | Higher tiers | Published overage |
|---|---|---|---|---|
| LangSmith | 1 seat, 5k base traces/mo | Plus: $39/seat/mo, 10k base traces | Enterprise: custom | Not published |
| Langfuse | 50k units, 30-day retention | Core: $29/mo, 100k units, 90 days | Pro $199/mo; Enterprise $2,499/mo | $8 per 100k units |
| Arize AX | 25k spans, 1 GB, 15 days | Pro: $50/mo, 50k spans, 10 GB, 30 days | Enterprise: custom | Not published |
| Braintrust | 1 GB, 10k scores, 14 days | Pro: $249/mo, 5 GB, 50k scores, 30 days | Enterprise: custom | $3/GB; $1.50 per 1k scores |
| Confident AI | 1 GB-month, 2 seats | Starter: $200/mo, 5 GB-months | Team $2,000/mo; Enterprise custom | $1 per GB-month |
We checked: LangSmith's pricing page says "pay as you go" with no per-trace rate, and Arize's doesn't describe overage at all. Five billing units in one category is, fittingly, an evaluation problem.
"We built Langfuse on ClickHouse because LLM observability and evaluation is fundamentally a data problem." — Marc Klingen, CEO, Langfuse, via Orrick
Which LLM observability tool fits which team?
Pick by framework, hosting rules and release process.
1. LangSmith is LangChain's tracing and evaluation platform, priced per seat; self-hosting is Enterprise-only. Docs
- Pros: built for LangGraph; online and offline evals
- Cons: overage rate unpublished; base traces kept 14 days
- Take: skip it outside LangChain.
2. Langfuse is an MIT-licensed observability, eval and prompt platform, acquired by ClickHouse in January 2026. Self-host · Docs
- Pros: core features free to self-host; transparent overage
- Cons: SSO and RBAC cost extra; you run the infrastructure
- Take: skip it if nobody will own the deployment.
3. Arize pairs self-hostable Phoenix with AX, a managed OpenTelemetry-based platform. Docs
- Pros: per-span and per-trace cost; Prompt Hub versioning
- Cons: ELv2 licence; AX self-host is Enterprise-only
- Take: skip it if you need OSI-approved open source.
4. Braintrust is an eval-first platform that versions prompts and promotes them through environments. Docs
- Pros: unlimited users on the free plan; per-span cost
- Cons: highest entry price; 14-day free retention
- Take: skip it if you only need tracing.
5. Confident AI is the hosted platform for DeepEval, an Apache 2.0 framework its repo calls "similar to Pytest but specialized for unit testing LLM apps." Docs
- Pros: metrics run in CI; chat simulations from Starter
- Cons: Free tier caps test runs; big jump to Team
- Take: skip it if you want observability before tests.
What changes when you evaluate a customer-facing agent instead of a prompt?
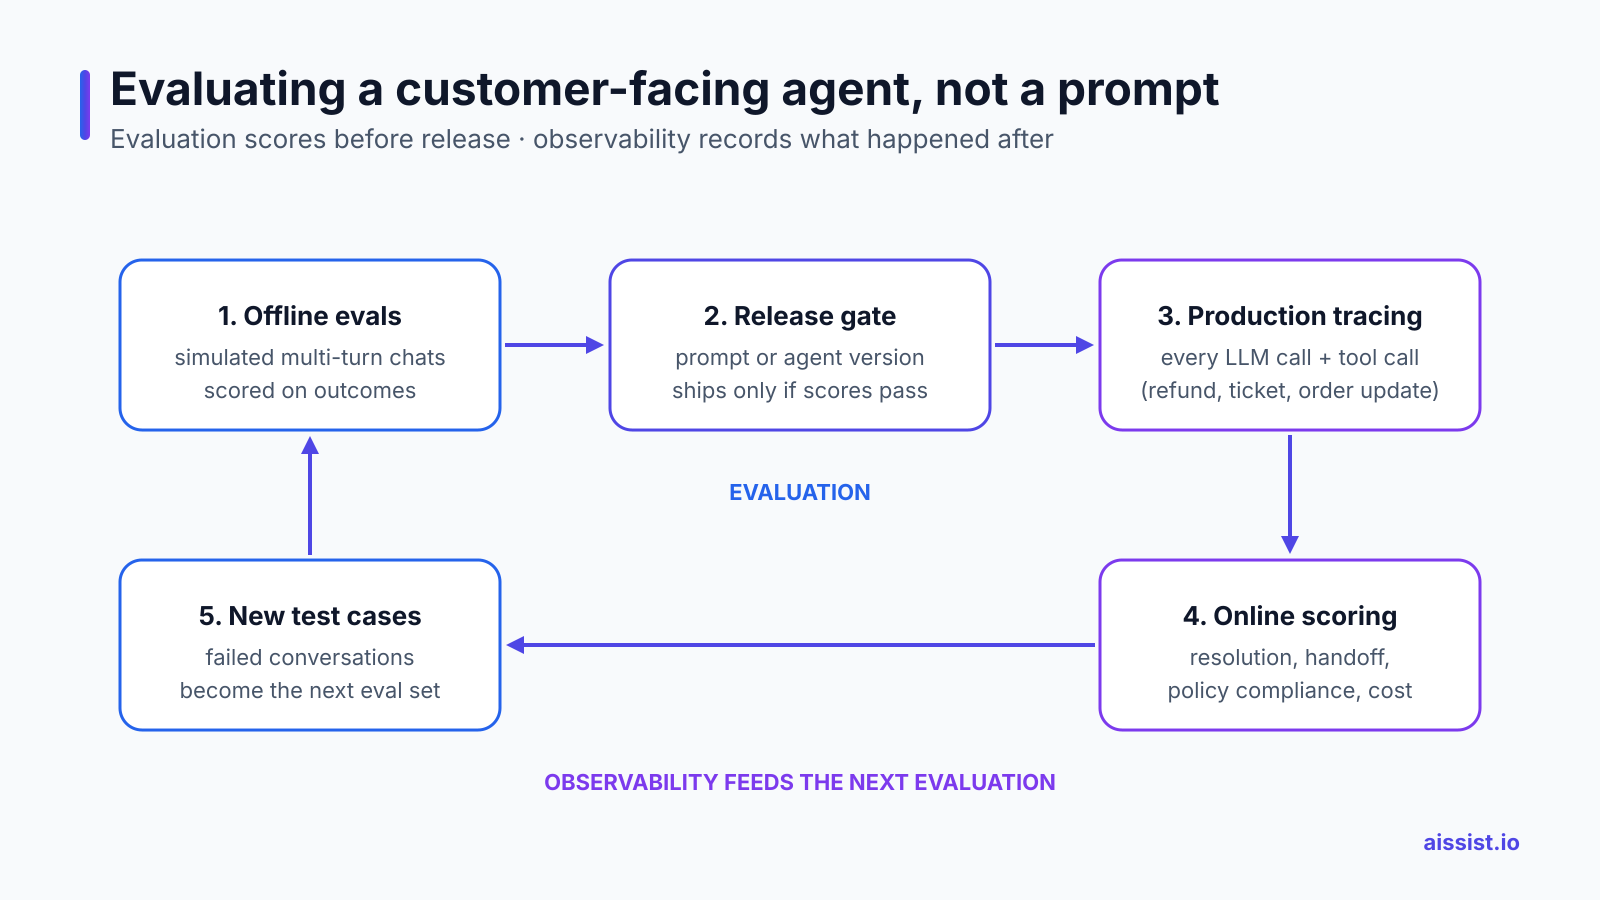
You score the whole conversation and what the agent did, not one completion. A prompt can be wrong. An agent can be wrong and then issue the refund.
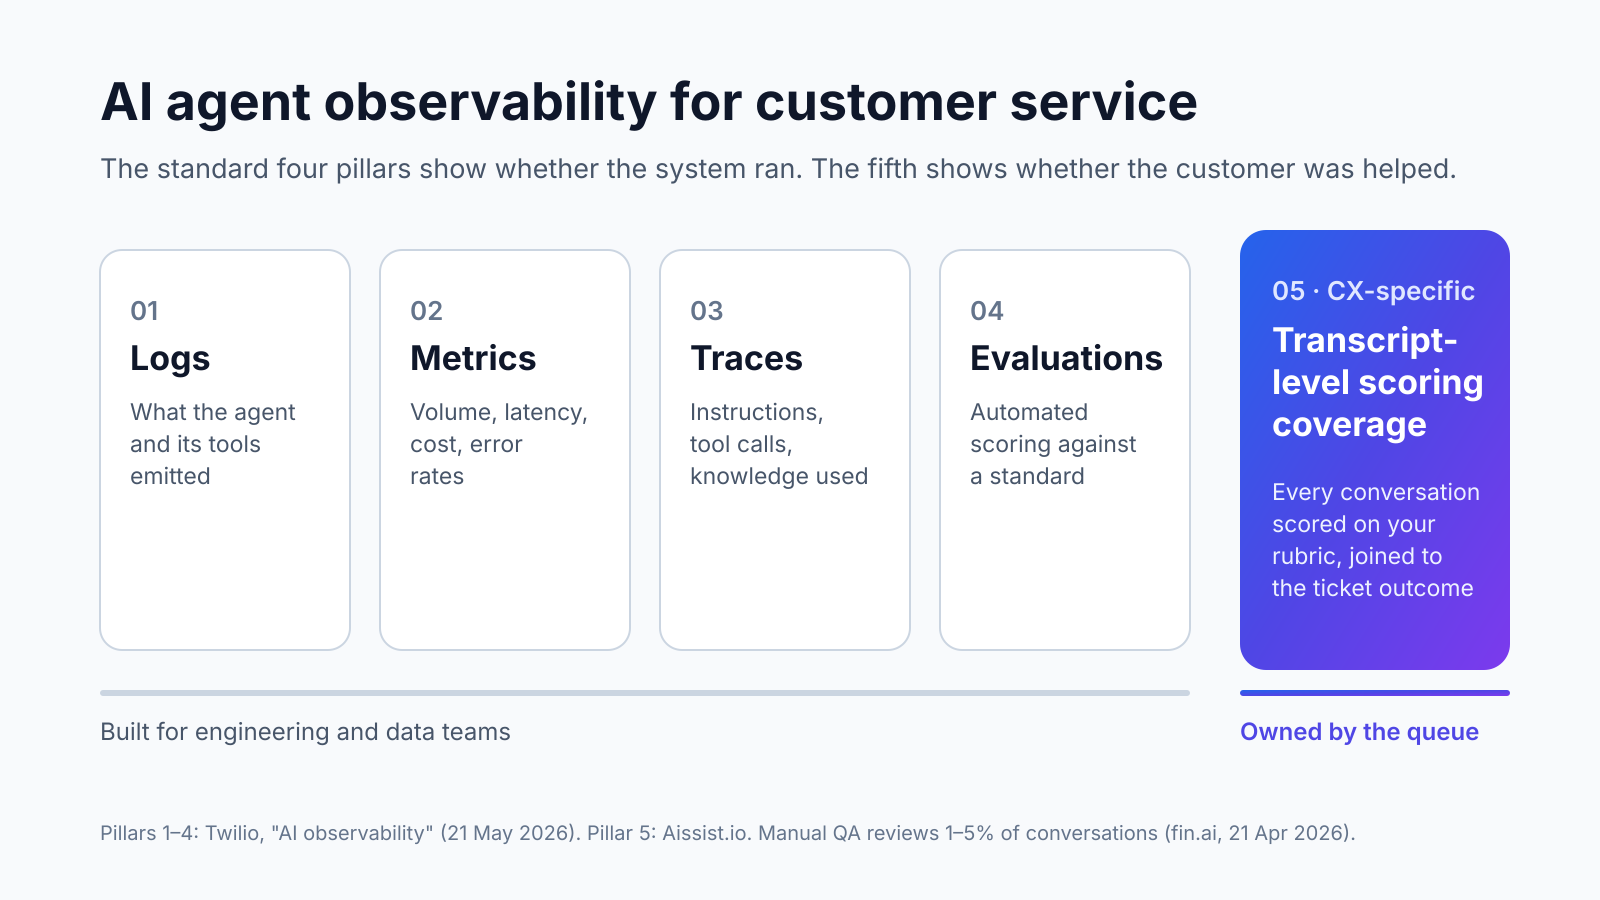
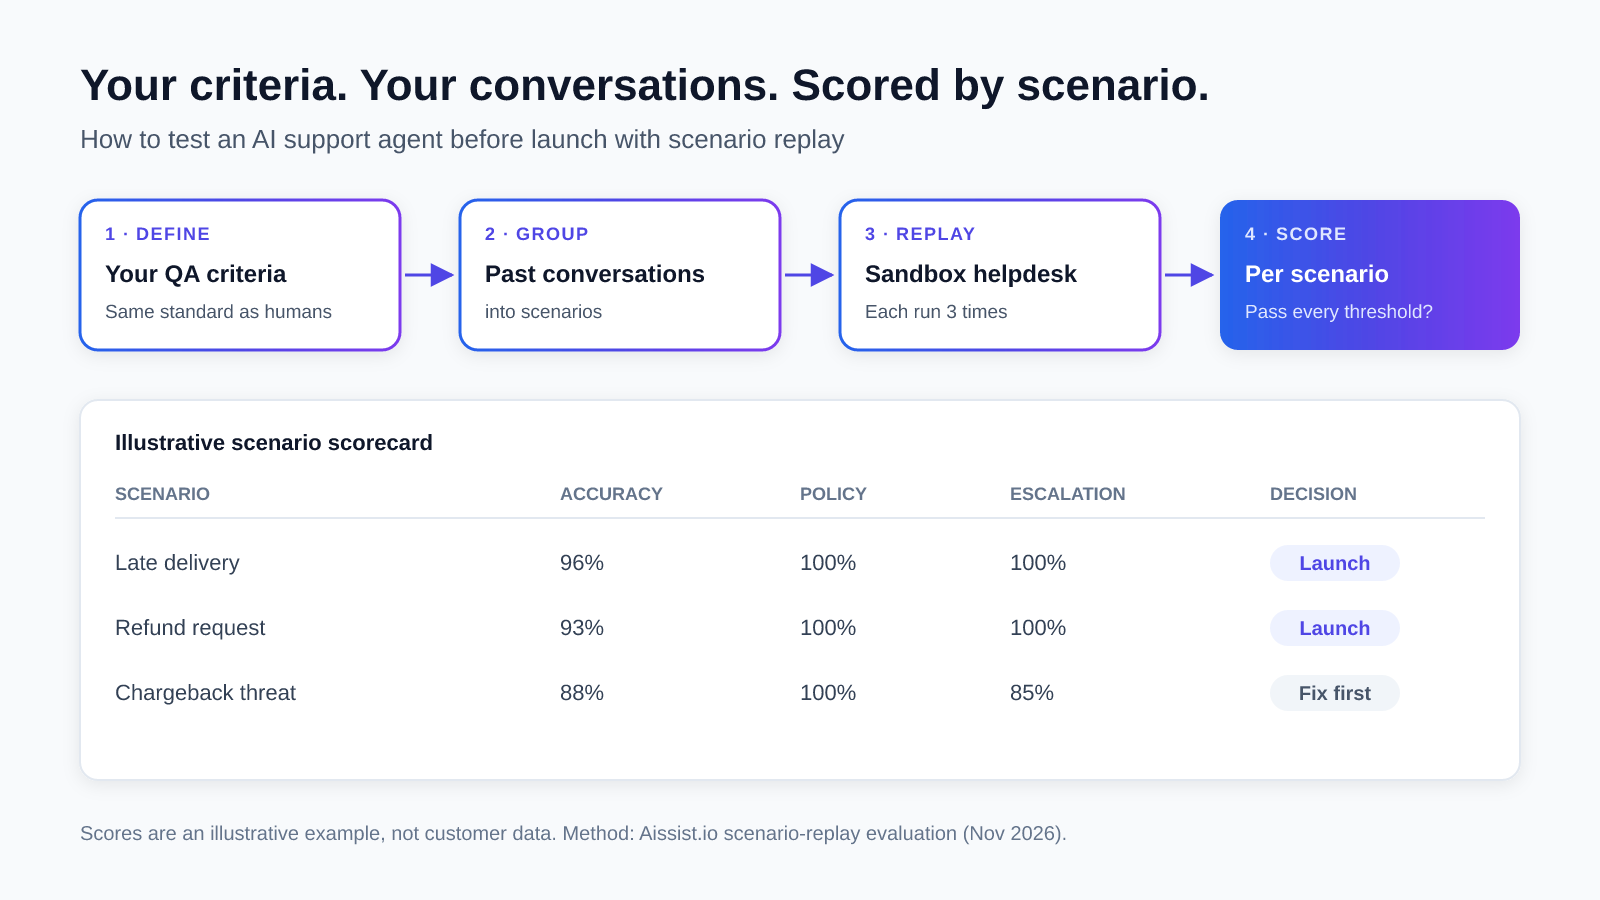
So traces must capture tool calls, evals must cover multi-turn conversations, and scores should measure outcomes: resolution, correct handoff, policy compliance. Support vendors agree: on 16 Nov 2026 Maven AGI shipped Maven Telemetry, which sends agent conversations to existing observability tools over OpenTelemetry.
"I've found that unsuccessful products almost always share a common root cause: a failure to create robust evaluation systems." — Hamel Husain, Your AI Product Needs Evals
More on support-agent observability, pre-launch testing and evaluable AI.
Verdict: pick on billing unit and hosting, then test on your own traces
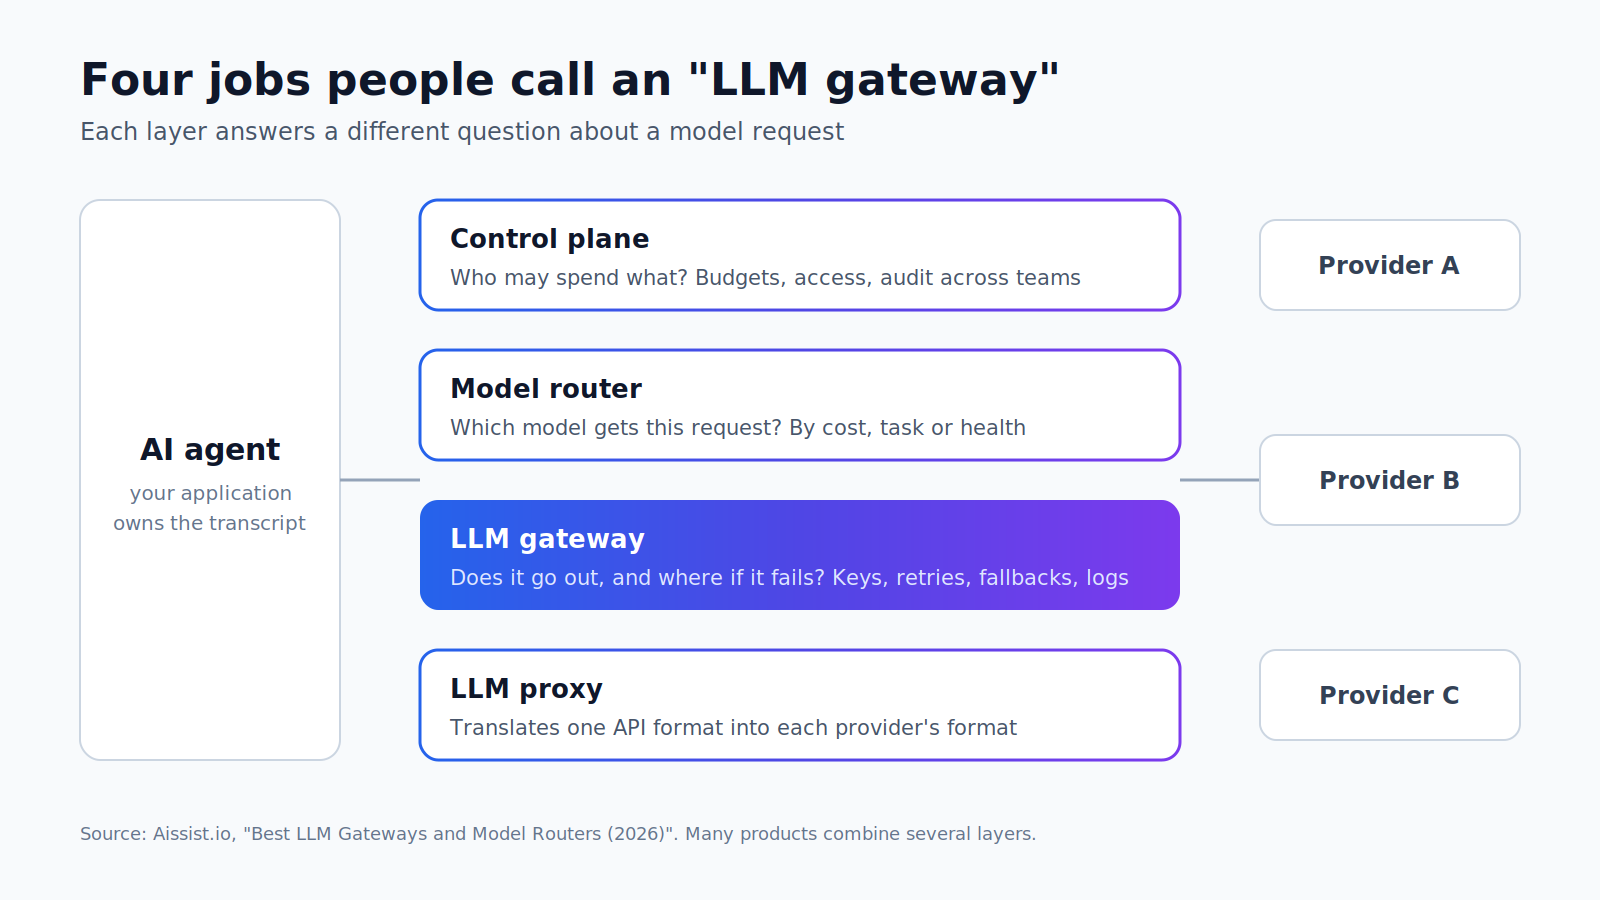
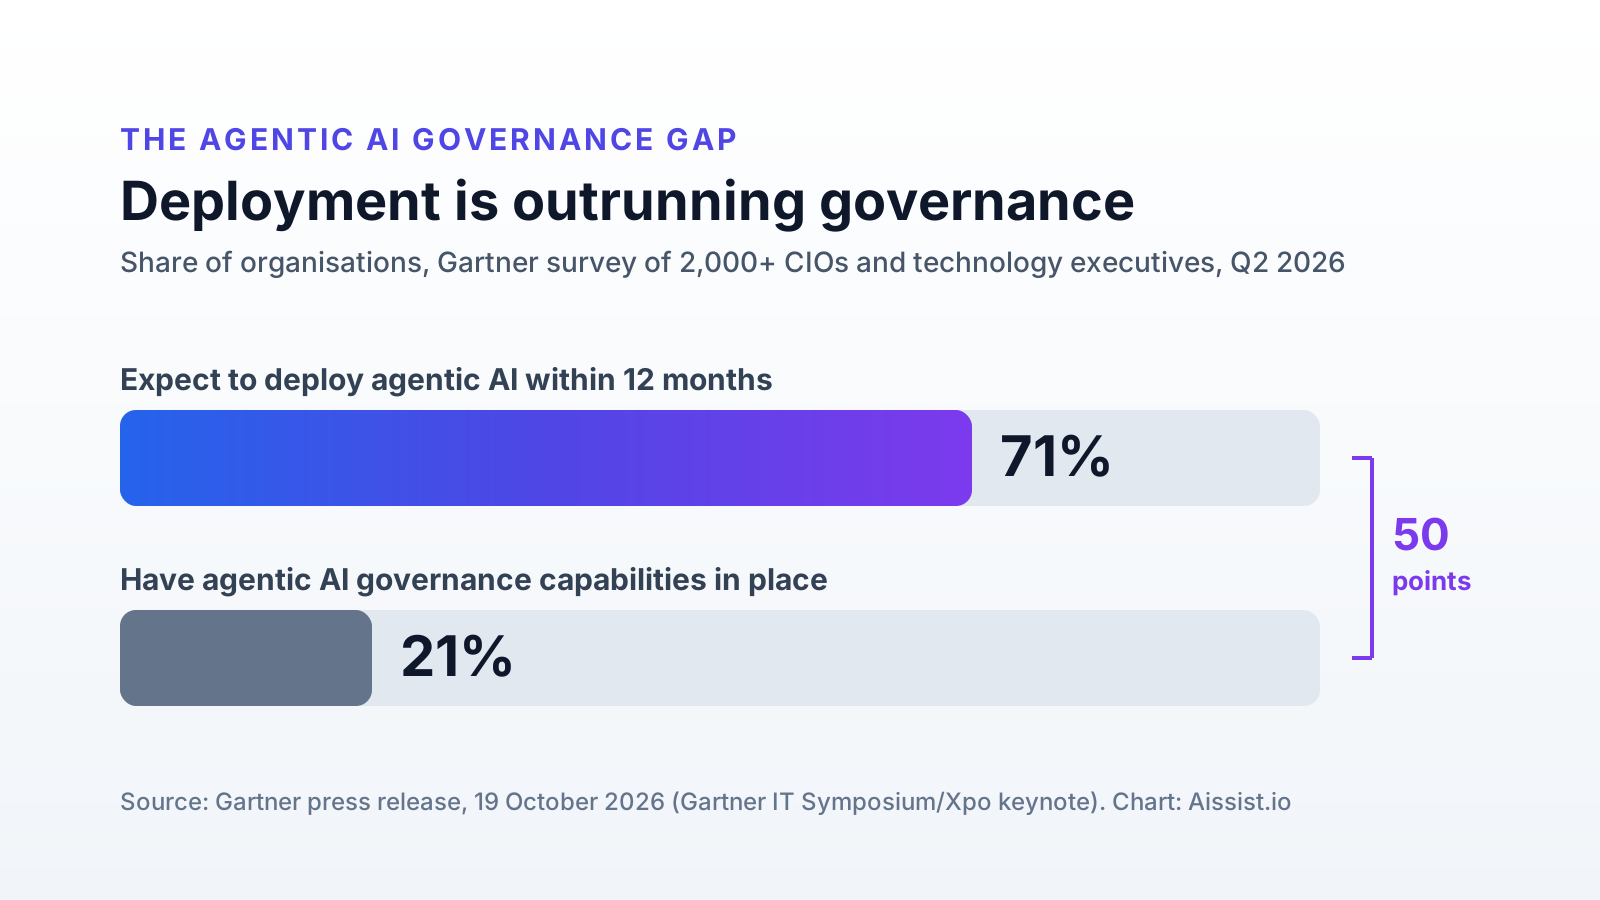
Free self-hosting? Langfuse. On LangChain? LangSmith. Evals gating every release? Braintrust or Confident AI. Then push a week of real traces through two free tiers before signing anything. Adjacent layers: LLM gateways and AI governance tools.
Frequently asked questions
What is the best open-source LLM evaluation tool?
Langfuse: its core platform is MIT-licensed and free to self-host. DeepEval (Apache 2.0) is open source too, but it is a testing framework, not a platform.
Which LLM eval platform is cheapest?
Langfuse Core, at $29 a month, is the lowest paid entry, and all five have free tiers. At scale, the billing unit matters more.
Do these tools evaluate AI agents, not just prompts?
Yes. All five trace multi-step agent runs, and Confident AI also simulates multi-turn chats.
Changelog
- 20 Nov 2026 — First published.